RSS and Atom let a reader app collect new posts for you; they are not email subscriptions. Opening these links in Safari may display plain text instead of a subscription form.
Choose Add feed or Subscribe in your reader (NetNewsWire calls it New Web Feed), then paste the RSS feed URL below. You can also use the Atom link above.
To copy manually, select the URL and press Command+C on Mac or Ctrl+C on Windows/Linux.
Find a post
Search published articles and forthcoming alpha previews together.
Search titles, keywords, and summaries. Accents and capitalization do not matter.
Loading search… The article list remains available below.
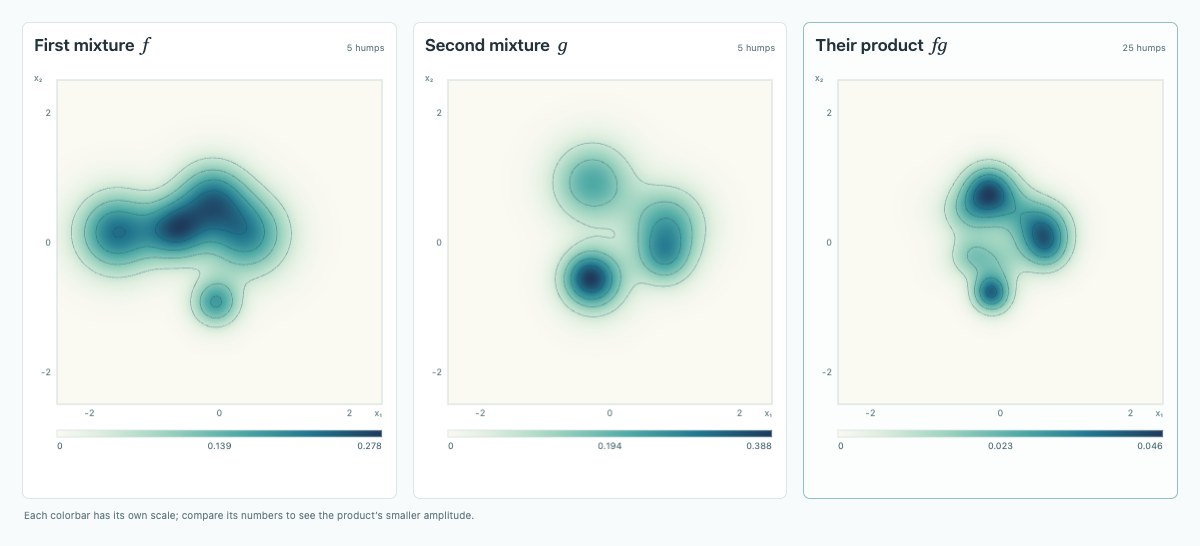
Multiplying two Gaussian bumps gives a smaller Gaussian bump. Yves Meyer's hump algebra turns this identity into a Banach algebra, with a scale-invariant atomic norm and an equivalent Besov norm.
Gaussian bumps are useful building blocks for signals and images: each has a location, a width, and an amplitude. Adding them creates complicated shapes. Multiplying them does something equally pleasant: two Gaussian bumps give another Gaussian bump, with a smaller width and an amplitude measuring their overlap.
Yves Meyer took this elementary observation seriously. Allow absolutely summable superpositions of translated and rescaled Gaussians, and measure a function by the least total amplitude needed to represent it. The resulting hump algebra, or algèbre des bosses, is a Banach algebra. Its connection to Besov spaces reveals that this apparently geometric description is also a precise measure of regularity across scales [1].
From exponential networks to two-layer MLPs, then from one output coordinate to a universal equivariant ConvNet. A short construction trades width for depth.
A fully connected neural network can approximate any continuous function on a compact set, provided its hidden layer is wide enough. What remains of this flexibility when the weights must be shared across space, as in a convolutional network?
The right target is a function with the same symmetry: shifting the input should shift the output. For finite periodic signals, the passage from MLP universality to ConvNet universality is remarkably short. A translation-equivariant map is determined by just one of its output coordinates. Approximate that coordinate by an MLP, and convolution applies the same computation at every position.
We will first prove shallow MLP universality through exponential networks and Stone–Weierstrass, then turn the proof into a convolutional one. Finally, we will see how to replace a wide hidden layer by a deep network with a constant number of channels.
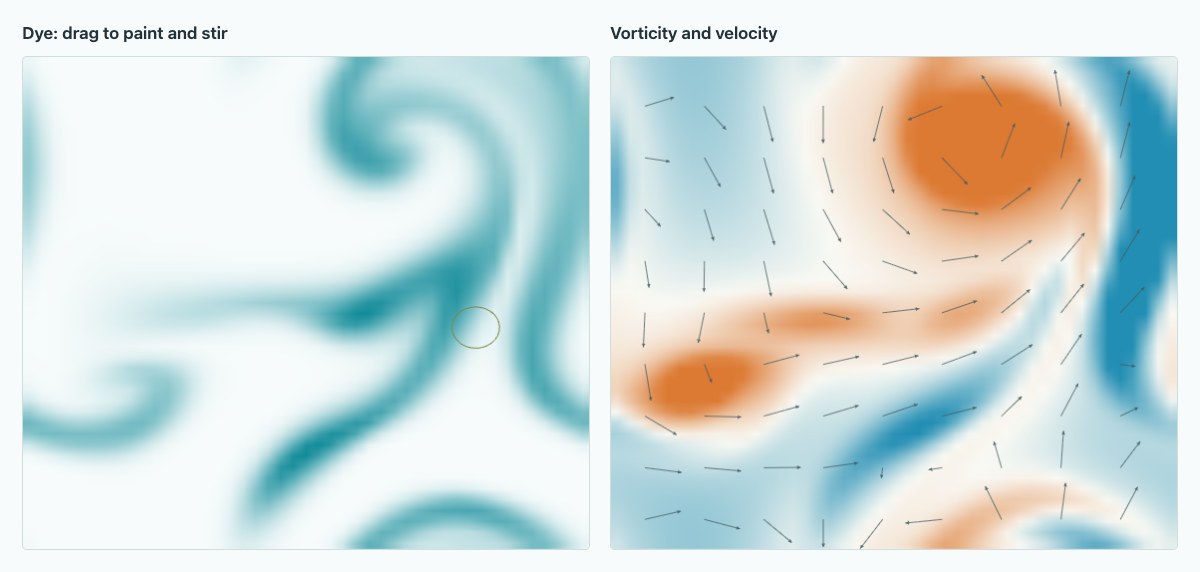
Stam’s Stable Fluids combines semi-Lagrangian advection, implicit diffusion, and an orthogonal incompressibility projection. Derive its Fourier solver and stir a periodic fluid interactively.
Stable Fluids is one of my favorite papers. Its blend of mathematics, numerical analysis, computer graphics, and physics has been a tremendous source of inspiration for me: a few elegant ideas become a simulation one can immediately see and interact with.
A moving cloud of smoke looks complicated. Its solver need not be. Jos Stam’s Stable Fluids[1] is built from a handful of operations with clear geometric meanings: carry a field along trajectories, smooth it, and enforce incompressibility by an orthogonal projection. Its achievement is an accessible synthesis for interactive graphics, built on a much older numerical-analysis tradition.
The trick is not to solve the entire fluid equation at once. Split it into manageable pieces, and choose each piece to avoid a familiar numerical instability. On a periodic domain, the pressure solve becomes particularly elegant: each Fourier coefficient is projected onto a line perpendicular to its wave vector. Stam’s later implementation notes [4] and Bridson’s book [5] are useful companions.
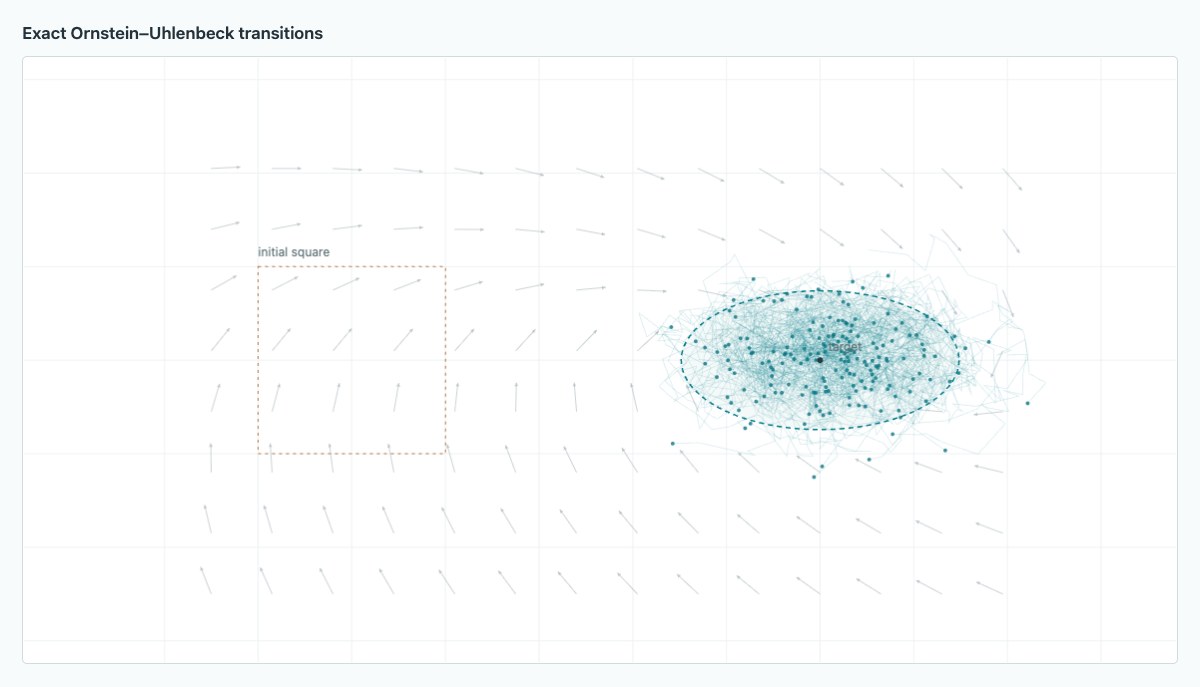
Langevin dynamics need not follow a potential. Confinement gives an invariant law; linear drift gives an exact Gaussian criterion, a Lyapunov covariance equation, and stationary circulation.
The usual recipe for Langevin sampling is to follow the negative gradient of a potential and add Brownian noise. The gradient pulls particles towards low energy; the noise prevents them from collapsing to a minimizer. Their balance produces a Gibbs distribution.
But a vector field does not have to be a gradient. Can a swirling, nongradient dynamics still settle into an equilibrium? Yes—and the distinction is instructive: confinement produces an invariant distribution, whereas reversibility is an additional property. A stationary distribution can carry a permanent probability current.
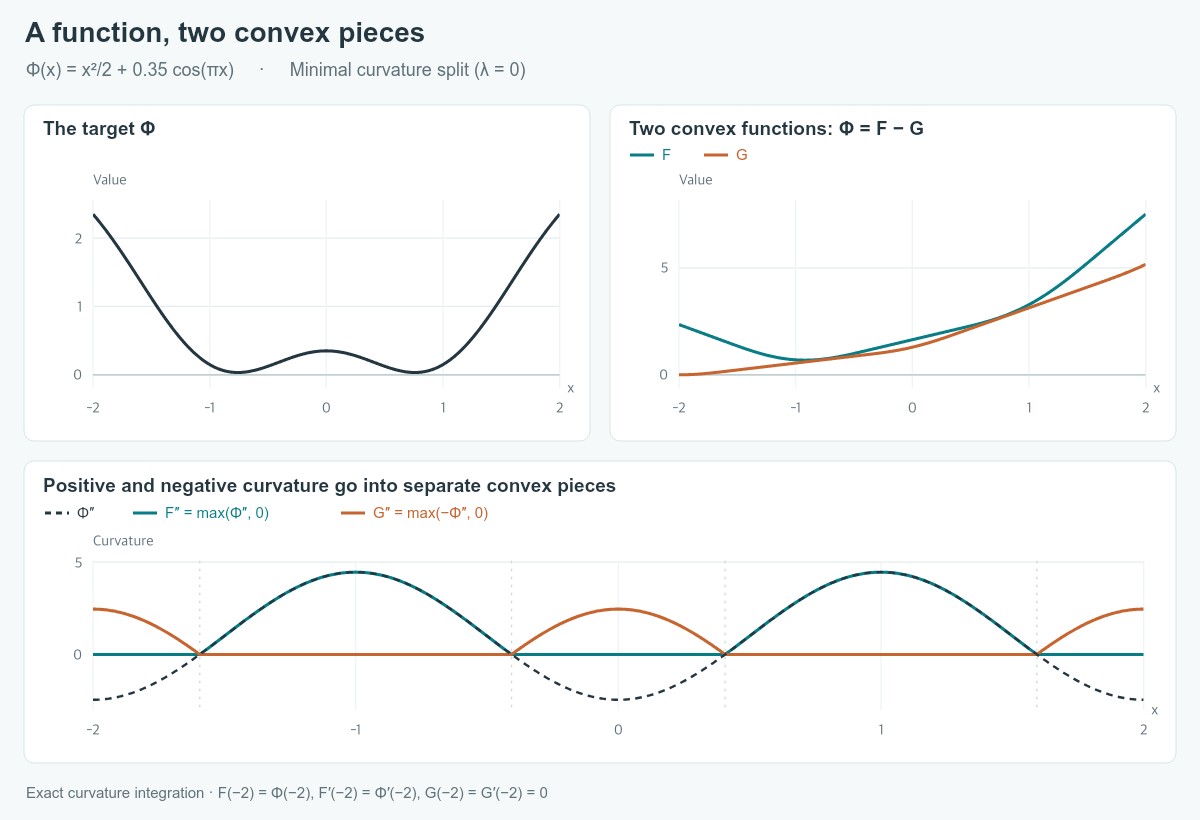
Difference-of-convex optimization, canonical curvature splitting in one dimension, nonunique minimal quadratic splits, and Toland duality, with an interactive decomposition and a nonconvex problem whose dual is convex.
Convex optimization is appealing because a local supporting plane contains global information. But many interesting objectives combine competing effects: a fidelity term and a sparsity incentive, attraction and repulsion, or positive and negative contributions to a transport energy. Subtracting two convex functions is already enough to leave the convex world.
The resulting class is called difference-of-convex, or DC, optimization. It retains enough structure to admit a beautiful duality: conjugate both convex functions, reverse their order, and minimize again. This is Toland duality [1], [2]. Following the viewpoint of Guillaume Carlier [3], I want to explain both its elementary mechanism and a particularly pleasant possibility: a genuinely nonconvex objective can have a fully convex dual.
The same construction also gives an algorithm. The key is to introduce a slope as an additional variable. Minimizing jointly gives the duality theorem; minimizing alternately gives the DC algorithm. But when the dual is convex, there is a third option: solve that convex problem directly, then recover a global solution of the original problem. This is the real prize—not merely another way to write the same stationary-point equations.
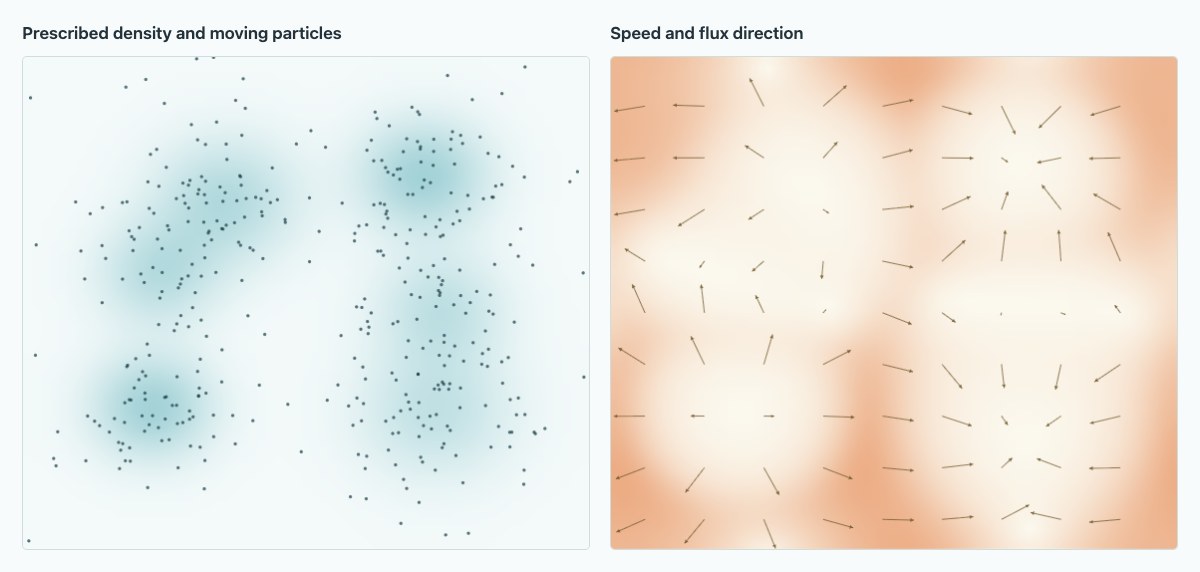
Moser’s construction turns a prescribed path of positive densities into moving particles: solve one Poisson equation, divide the flux by the density, and integrate a flow.
Two pictures of a probability distribution suggest two different ways to interpolate it. One can blend their densities, as in a cross-fade. Or one can move the particles, carrying every bit of mass from its starting point to a destination. Can these pictures describe exactly the same evolution?
Moser’s construction gives a beautiful affirmative answer for smooth, strictly positive densities. Prescribe the density path, solve a divergence equation for its flux, then divide by the density to recover a velocity. The nonlinear-looking transport problem reduces to one Poisson solve and an ordinary differential equation. The idea originates in Moser’s theorem on volume forms [1]; Dacorogna and Moser developed the prescribed-Jacobian problem further [2].
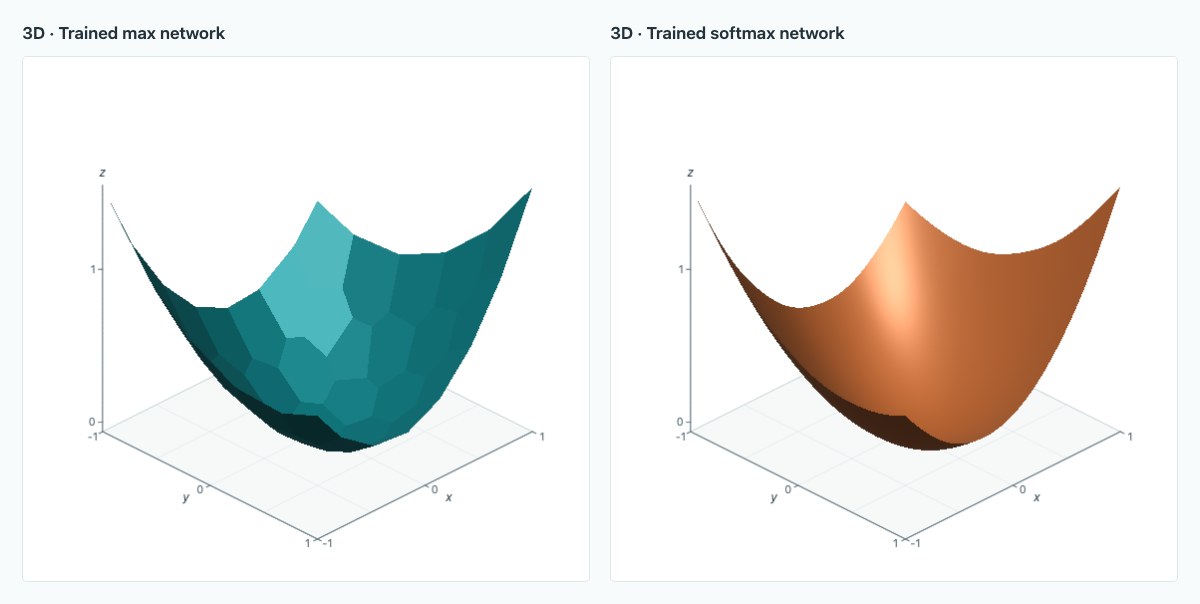
Constructive universal approximation of convex functions by max-affine and log-sum-exp networks, with proofs, rates, and interactive experiments.
When learning an energy, it is often worth building its geometry into the model. A convex objective has no spurious local minima on a convex domain, and many algorithms can exploit that structure. In quadratic optimal transport, the optimal map is the gradient of a convex potential when the source measure has a density and both measures have finite second moments. These are good reasons to use neural architectures that represent convex functions by construction [7], [8].
One architecture is especially transparent: compute several affine functions, then take their maximum. To approximate a convex target, choose these functions as supporting planes; their maximum forms a polyhedral surface beneath the graph. Replacing the maximum by a log-sum-exp gives a smooth surface. We will separate three questions: can these networks approximate every convex function, how many planes are needed, and what does smoothing cost?
A rigorous counterexample shows that Gaussian marginals need not admit a jointly Gaussian optimizer for squared-distance Gromov–Wasserstein transport.
Gaussians are wonderfully cooperative in quadratic optimal transport: when the source is nondegenerate, an affine map solves the transport problem, and the answer can be expressed using means and covariance matrices. It is tempting to carry this intuition into Gromov–Wasserstein transport, where the task is to match relations between pairs of points.
That intuition has a limit. A pair of Gaussian marginals need not admit a jointly Gaussian optimal coupling. The example below makes the obstruction explicit: linear correlation has a bounded budget, while correlating the radii can exploit fluctuations that grow with dimension.
The construction is recorded in Proposition 13.34 of Optimal Transport for Machine Learners[1]. The Gaussian-constrained problem and the question of unrestricted optimality are studied by Antoine Salmona, Julie Delon, and Agnès Desolneux [2]. We will prove the strict separation directly, without claiming a formula for the unrestricted optimizer.
An elementary exactness identity for quadratic optimization, its extension to regularized objectives, and its role in Gromov–Wasserstein computation.
When an optimization problem is difficult because a variable interacts with itself, a tempting idea is to introduce a second copy. Replace a quadratic term \(x^{\mathsf T}Qx\) by a bilinear term \(x^{\mathsf T}Qy\), and optimize alternately over \(x\) and \(y\). Each step is much simpler. But have we changed the problem? What prevents the two copies from exploiting their new freedom?
Hiroshi Konno identified a particularly elegant answer for convex quadratic maximization, or equivalently concave quadratic minimization [1]. Under the appropriate sign condition, releasing the equality \(x=y\) does not change the optimal value. Better still, either component of an optimal pair solves the original problem. The reason fits in a single quadratic identity.
With Thibault Séjourné and François-Xavier Vialard, we used an extension of this idea in our work on unbalanced Gromov–Wasserstein transport [3]. The extension permits a general additional term, including entropy. Let us first isolate the elementary principle, then see what it does—and does not—say for transport algorithms.
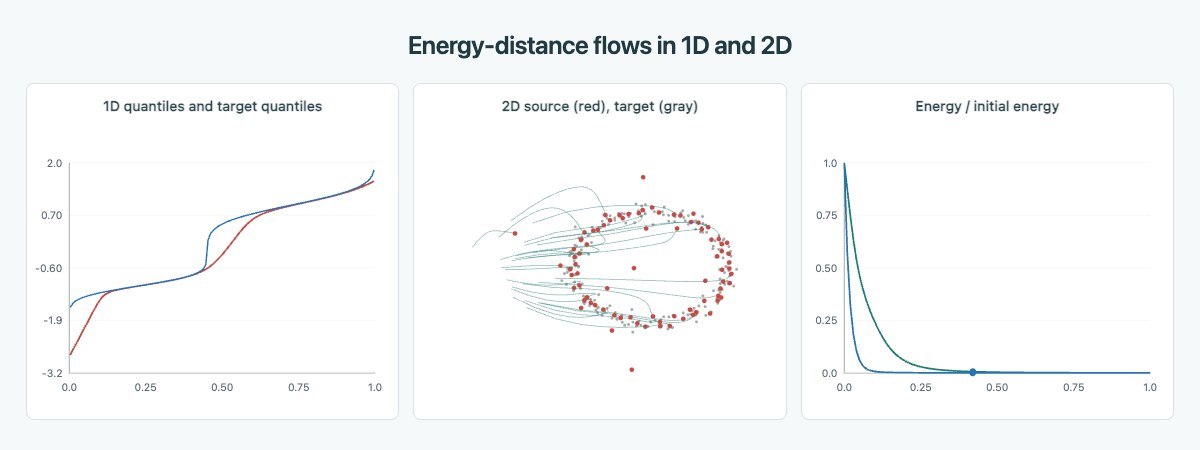
Why the energy distance is Wasserstein convex on the line, how its quantiles evolve, and an explicit two-dimensional counterexample.
Suppose we want to move a distribution towards a target. A natural loss attracts its points towards the target while repelling them from one another: attraction finds the right location, and repulsion prevents everything from collapsing to a single point. The energy distance implements exactly this idea using ordinary Euclidean distances.
Looking at the repulsive interaction, one might expect a difficult nonconvex problem. On the real line, however, its Wasserstein geometry is particularly simple: the repulsion is linear in quantile coordinates, and the whole objective is convex. The explanation has less to do with smoothness than with the fact that particles can be ordered. This is the mechanism behind the interaction criterion in Proposition 15.18 of my book[1] and the quantile-flow analysis of Duong and collaborators [2].
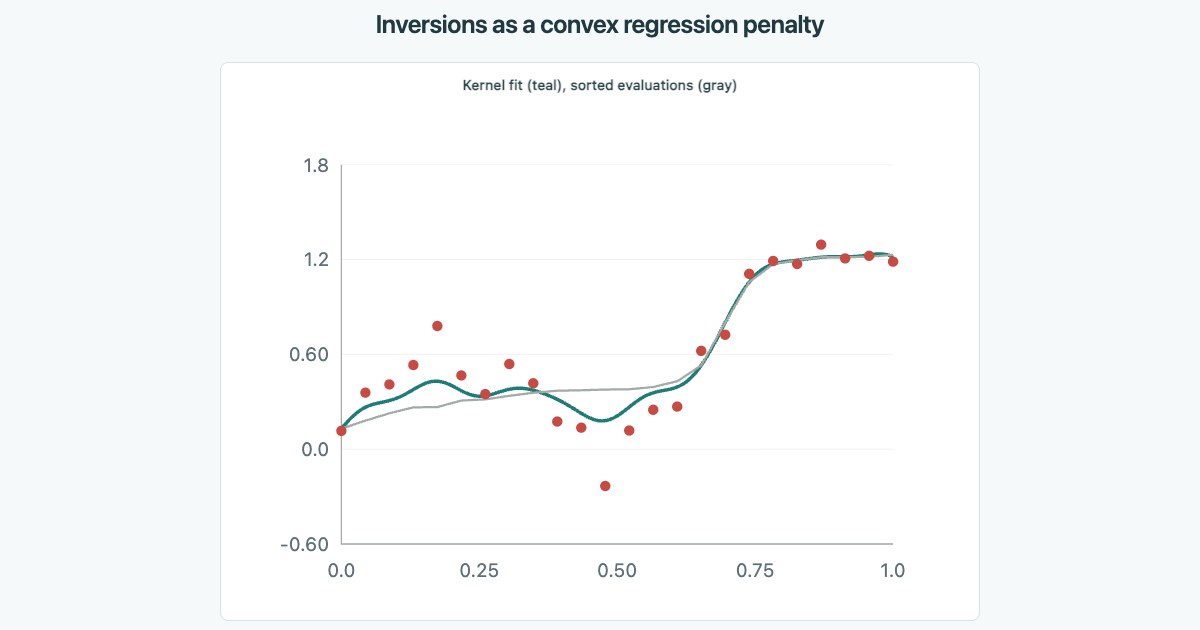
A quantitative rearrangement identity turns the Monge gap into a sum of hinge penalties, with an application to convex kernel regression.
Imagine fitting a response curve to noisy observations. You want a flexible model, but you also expect larger inputs to produce larger outputs. Smoothness alone does not enforce this: a perfectly smooth curve can run in the wrong direction. Optimal transport suggests a different penalty, one which measures how much a map would improve if we reassigned its outputs.
This is the Monge gap, introduced as a learning regularizer by Théo Uscidda and Marco Cuturi [1]. In one dimension, it has a particularly transparent meaning. On a uniform input grid, it is exactly a sum of penalties for inverted pairs. The identity in Proposition 3.44 of Optimal Transport for Machine Learners[2] makes a transport-based regression problem an ordinary convex optimization problem.
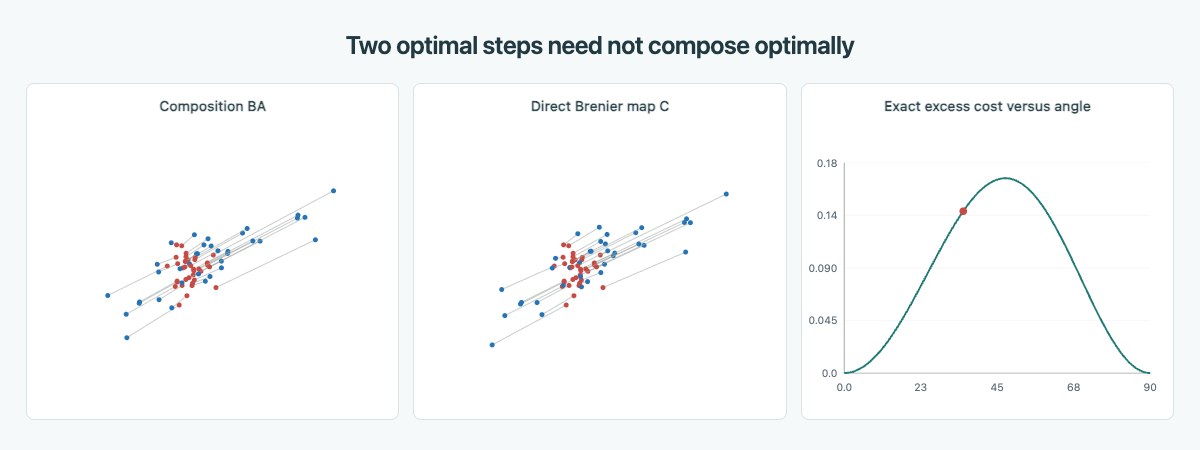
Two quadratic optimal maps need not compose into an optimal map. A matrix example separates monotonicity, convex gradients, and optimality.
Transport a distribution optimally to an intermediate distribution, then transport that one optimally to a final target. Is the resulting correspondence optimal between the original and final distributions? On the real line, yes: increasing maps compose into increasing maps. In higher dimensions, the answer is generally no.
This is more subtle than saying that a journey through a waypoint can be long. Here we compare the direct endpoint displacement of the composed map with the direct optimal cost. The composition itself may assign the wrong endpoints. A two-dimensional Gaussian example explains why, and also clarifies a common confusion between monotone maps and gradients of convex functions. See Remark 2.42 of my book[1].
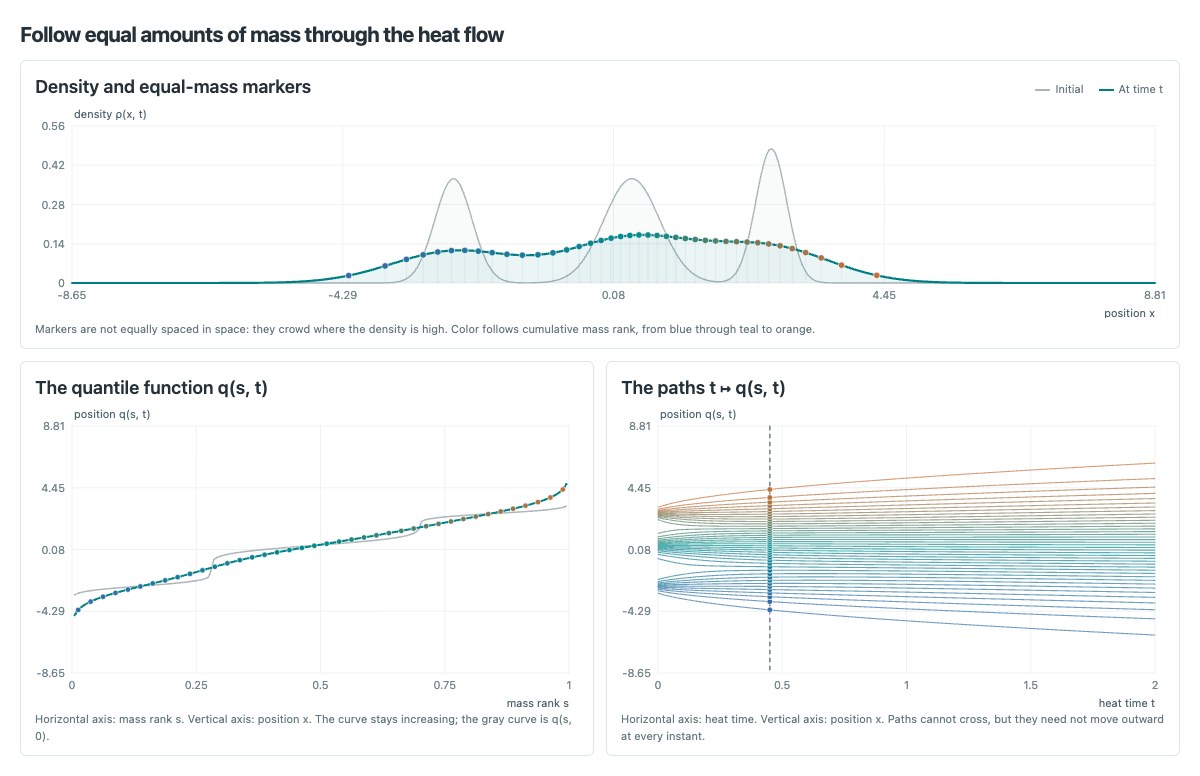
Quantiles turn one-dimensional Wasserstein geometry into L2 geometry. The JKO entropy step then yields a nonlinear quantile formulation of heat, illustrated by a three-Gaussian mixture.
The heat equation spreads a density through space. In one dimension, there is another way to watch it: follow the median, the first quartile, or any fixed fraction of the mass. These positions trace deterministic, ordered paths, even though heat can also be described by random Brownian motion.
The Jordan–Kinderlehrer–Otto formulation makes this change of viewpoint particularly transparent. Heat is the Wasserstein gradient flow of negative entropy [1]. Quantiles turn the one-dimensional Wasserstein distance into an ordinary \(L^2\) distance. Put these two facts together, and the familiar linear heat equation becomes a nonlinear equation for a single increasing function.
An exact criterion for independent sampling to solve optimal transport, with a short centered-interaction proof, orthogonal supports, and the high-temperature limit of entropic transport.
The simplest way to couple two distributions is to sample them independently. No matching algorithm, no sorting, no optimization: draw \(X\sim\alpha\) and \(Y\sim\beta\) independently. Their joint law \(\alpha\otimes\beta\) always has the desired marginals.
Could this effortless coupling already be an optimal transport? Under compactness and continuity assumptions, there is an exact answer: only when every coupling has the same cost. The cost must separate into a source-only term plus a target-only term on the two supports. The statement is Proposition 3.29 of my book[1]. Its proof can be made very short by subtracting the row and column means of the cost.
Stone–Weierstrass through polynomials, Fourier modes, and exponential networks: approximate products prove deep ReLU universality, and explicit exponential interpolation proves two-layer universality.
The Stone–Weierstrass theorem is a cornerstone of approximation theory: it turns a few structural properties of a family of functions into the ability to approximate every continuous function. It explains the density of polynomials and Fourier modes, and provides a route to universality for neural networks—even two-layer networks. It also plays a central role in my recent work with Takashi Furuya and Maarten de Hoop on attention universality over an infinite-dimensional space of contexts [3].
The hypothesis that often looks most restrictive is stability under products. Multiplying two polynomials gives another polynomial, but multiplying two ReLU networks generally does not give a ReLU network. Fortunately, exact multiplication is unnecessary: it is enough that products belong to the uniform closure of the class. This elementary consequence of the usual theorem is worth keeping in mind.
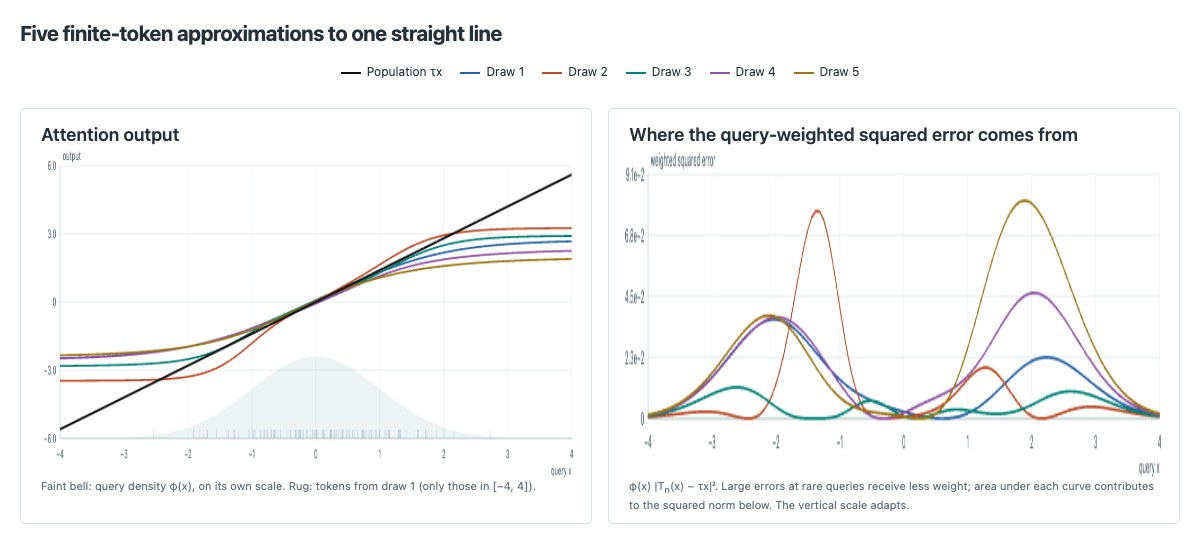
Why finite-token attention can converge slowly despite a pointwise square-root rate: exponential query sensitivity, a radius–tail tradeoff in L2, and interactive Gaussian attention curves.
Suppose an attention head has already been trained. Keep its weights fixed, but give it more and more tokens sampled from the same distribution. How quickly does its output stabilize? Equivalently, how many sampled keys do we need to approximate attention over a very large context?
This is the question of token sample complexity, which we study with Léa Bohbot, Cyril Letrouit, and François-Xavier Vialard in our recent paper [1]. It concerns the number of tokens used at inference, not the number of examples used to train the model. There is also beautiful, independent and concurrent work by Etienne Boursier and Claire Boyer on this same question [2].
The apparent paradox is simple. For Gaussian or sub-Gaussian tokens, attention at a fixed query has the familiar Monte Carlo scale \(n^{-1/2}\). But the constant can grow exponentially as the query moves away from the origin. To control the error over an entire token distribution, we must balance these increasingly difficult queries against their increasingly small probability. We will make this tradeoff explicit for one-dimensional Gaussians.
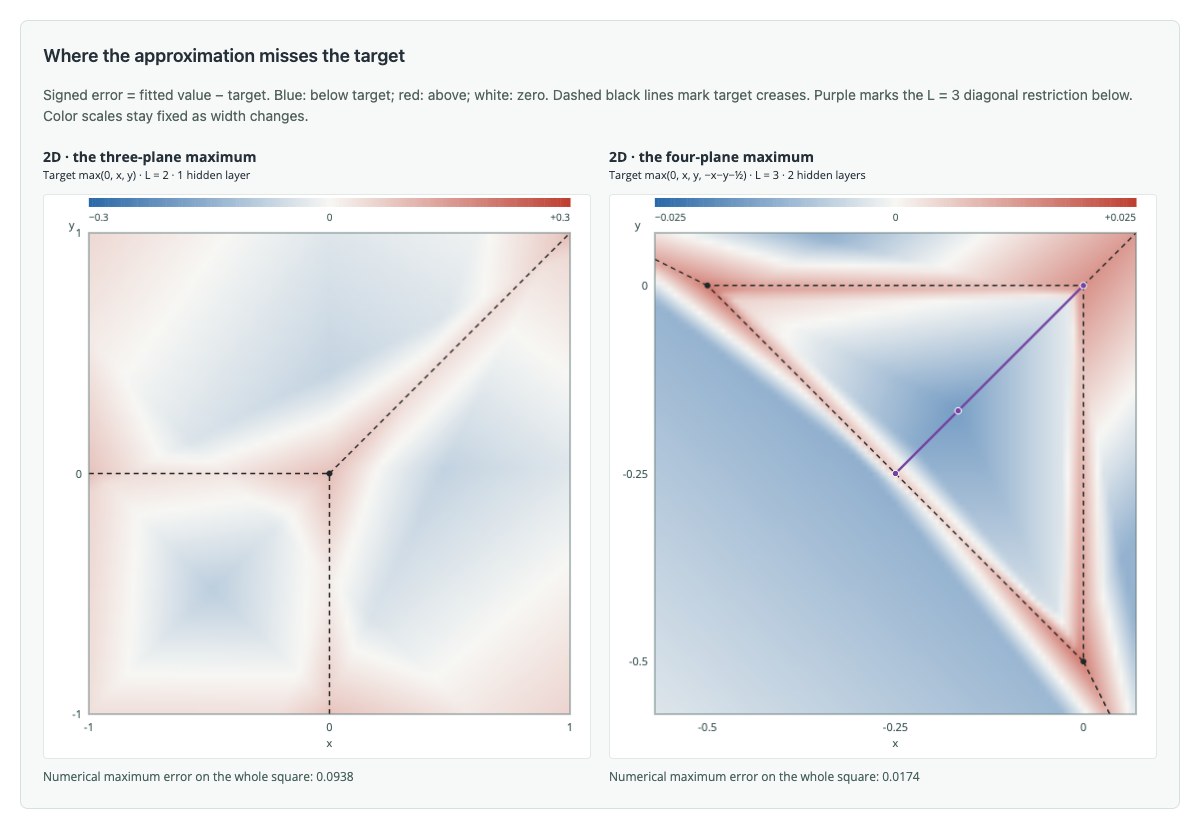
Why no fixed depth makes ReLU ICNNs universal in dimension two: explicit counterexamples, expandable proofs, triangular-grid witnesses at larger depths, and interactive numerical comparisons.
Neural networks are flexible representations of functions. But what if the function must be convex? This constraint is especially natural in optimal transport. For probability measures with finite second moments and an absolutely continuous source, Brenier’s theorem identifies the quadratic optimal transport map as the gradient of a convex potential [1], [2]. Learning such a potential is therefore a way to learn a transport map while respecting its geometry.
Input-convex neural networks, or ICNNs, enforce convexity through their architecture [3]. A natural question follows: can they approximate every convex function? Yes, if depth is allowed to grow with the desired accuracy [4]. But in dimension two, no fixed depth suffices. We start with two explicit counterexamples on a square, for one and two hidden ReLU layers, then give a self-contained proof of the obstruction at every fixed depth.
Universality means reaching every prescribed uniform error by increasing the network’s size. Its failure is compatible with a good fit at a fixed tolerance: the obstruction can be small enough to escape a plot of the function values. The second example below illustrates this distinction particularly well.
Which transport costs preserve optimal plans under a common translation? A characterization by the mixed Hessian, a short proof, and quadratic, cubic, and exponential examples.
If we translate two point clouds by the same vector, should their optimal transport plan simply translate along with them? For a cost such as the squared Euclidean distance, the answer is immediate: every pairwise displacement stays the same. But this is only one way for the optimal matching to be preserved.
The more interesting question is to characterize all costs whose optimal plans commute with translations. A cost may change without changing its minimizers: multiplying it by a positive constant or adding terms that depend on the source point alone or the target point alone has no effect on the optimizer. Under suitable nondegeneracy assumptions, these two freedoms give the complete answer.
From balancedness in linear networks to conserved functionals of a neuron distribution: a covariance formulation, a short proof, and its role in convergence.
While working with Stephen Zhang on the convergence of two-layer linear networks, we made use of a construction I find particularly appealing: mean-field conservation laws. These are functionals of the neuron distribution that remain constant during training. The same functional works for every number of neurons, and also for a continuous distribution describing an infinite-width network.
In our recent preprint, the relevant laws depend only on the neurons’ second moments. They turn a familiar conservation principle, balancedness, into a statement about a matrix whose size does not grow with the network. This gives a way to control the geometry of training and prove convergence.
Barycentric projection of transport couplings in fiberwise Wasserstein geometry, with quadratic and entropic optimality proofs, the modified-target caveat, weak transport, and an interactive unequal-cardinality example.
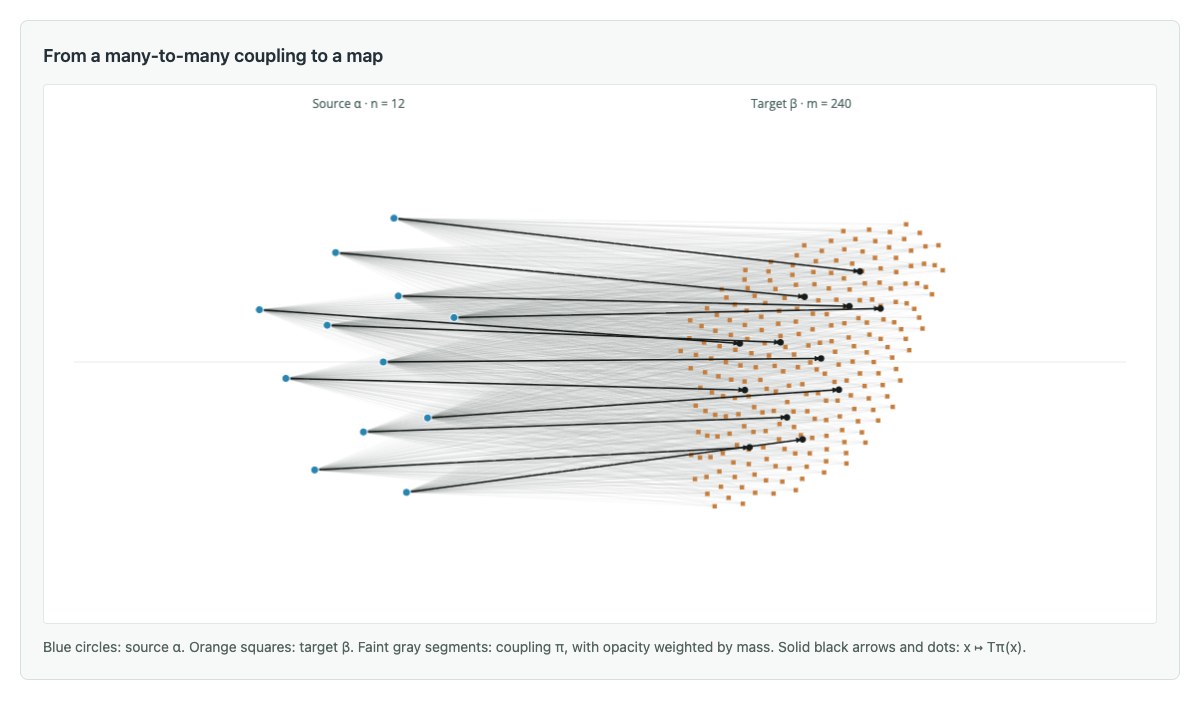
How do you turn a transport plan into a map? This question appears as soon as we transport a small point cloud to a much larger one: the Kantorovich solution splits each source point’s mass among several destinations. Entropic regularization makes that splitting even more explicit.
The barycentric projection replaces those destinations by their conditional mean. For an arbitrary coupling, the resulting map need not be optimal. If the coupling solves quadratic Kantorovich OT or quadratic entropic OT, however, its barycentric projection is an unregularized quadratic Monge map—but to its own image measure, not generally to the original target. In the entropic case, this follows from a smooth convex log-sum-exp potential derived from the optimal dual potentials.
The convex optimality gap as a Fenchel–Young loss, with an interactive inverse optimal transport experiment between two Gaussian mixtures and a linked bibliography.
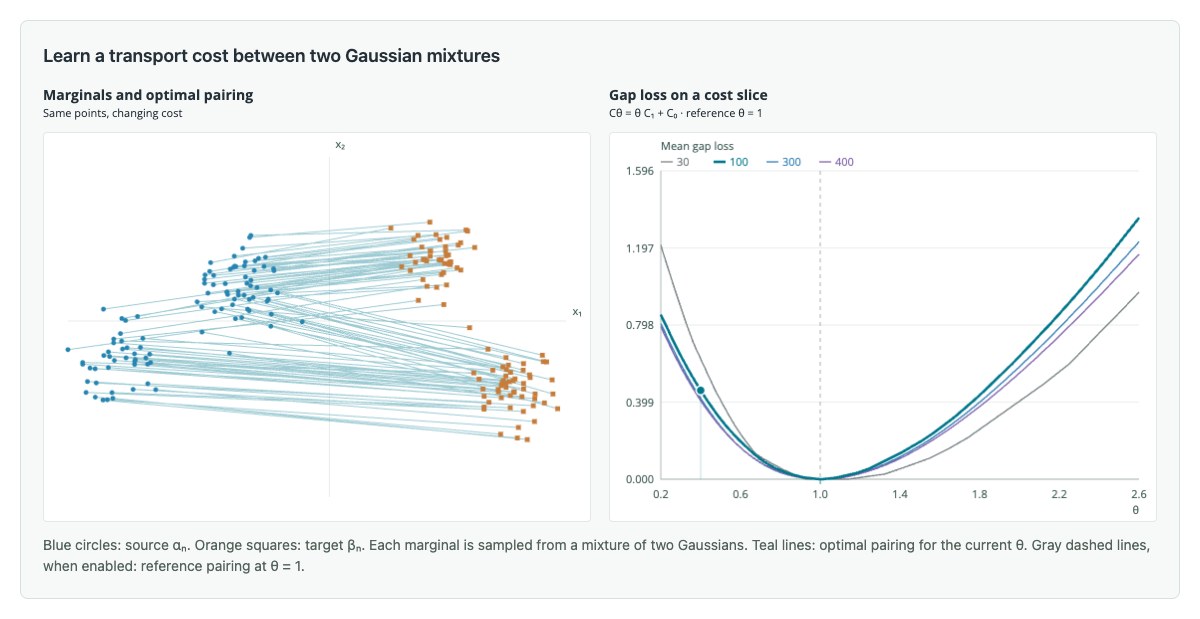
In an optimisation problem, we know the objective and look for the best decision. In inverse optimisation, we observe decisions and try to recover an objective that explains them. Inverse optimal transport (iOT) is one example: rather than computing a coupling from a cost, we learn a cost from an observed coupling.
A useful measure of disagreement is the gap loss: the cost of the observed decision minus the cost of the best decision. When the objective depends linearly on the parameter to learn, this loss is convex—even if the forward optimisation problem is not. This is closely connected to Fenchel–Young losses. The interactive experiment below explores the gap for transport between two mixtures of Gaussians.
Gelbrich's Gaussian contraction and a criterion explained by Hugo Lavenant, with proofs for Gaussian relative entropy and heat flow.
I share many things with my colleague, friend, and office mate (well, not this year!) Olivier Cappé, including a love of Gaussians.
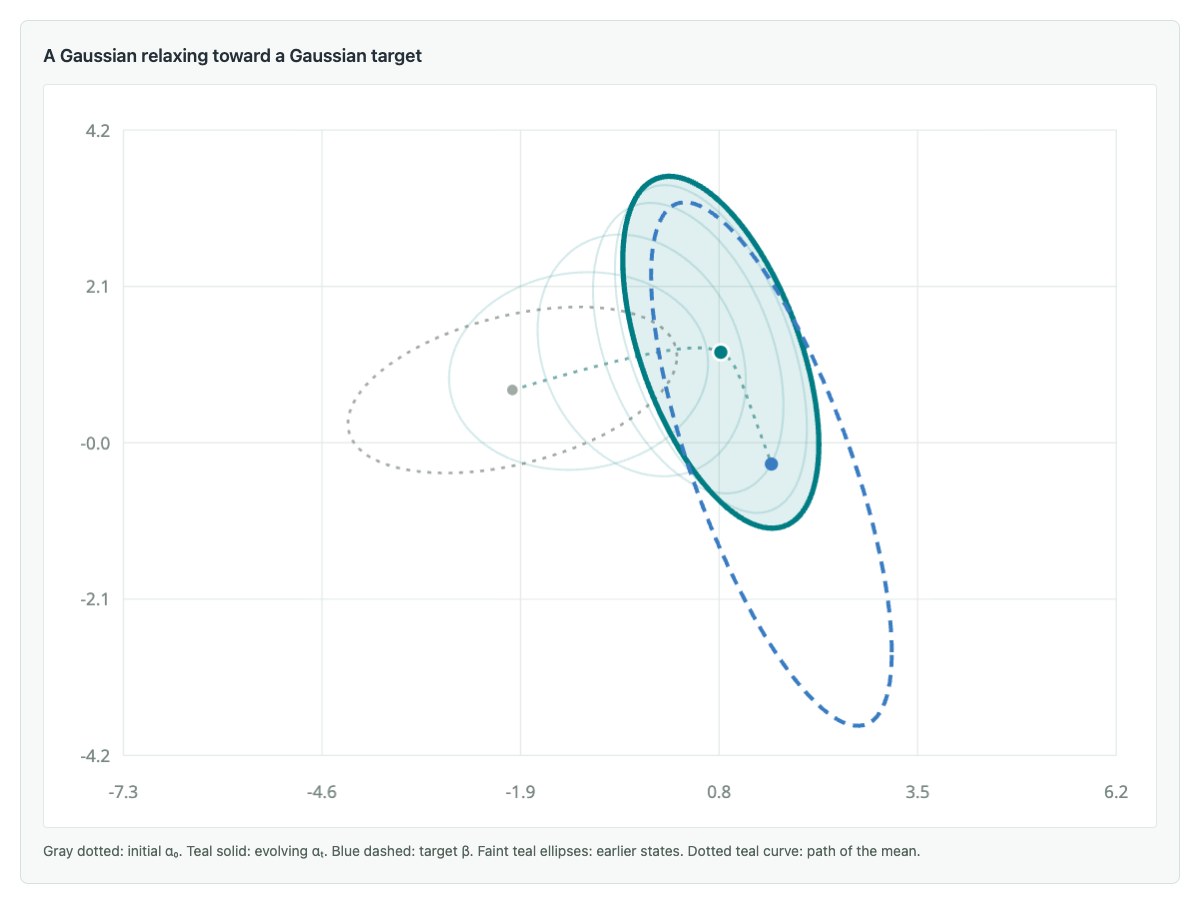
I especially love PDEs that preserve Gaussians—and, more specifically, Wasserstein gradient flows that do so. An infinite-dimensional evolution of a probability density then reduces exactly to the evolution of a mean vector and a covariance matrix.
Une clarification de mon intervention sur France Inter, en français et en anglais.
J’ai été interviewé pour la chronique Nos vies numériques de France Inter du 10 septembre 2026, consacrée à l’intelligence artificielle et aux équations de Navier–Stokes. Mon intervention a été fortement raccourcie — ce que le format très court de la chronique peut expliquer — et l’extrait diffusé ne reflète pas l’ensemble de ma pensée.
Oui, les progrès récents de l’IA sont passionnants. On entrevoit de nouvelles façons de faire des mathématiques, qui ouvriront très vraisemblablement la voie à des avancées majeures. Mais cet enthousiasme ne peut pas être séparé des questions qu’ils soulèvent pour la recherche et l’éducation.
Why a gradient inequality can be enough for exponential convergence, illustrated by an interactive curved valley.
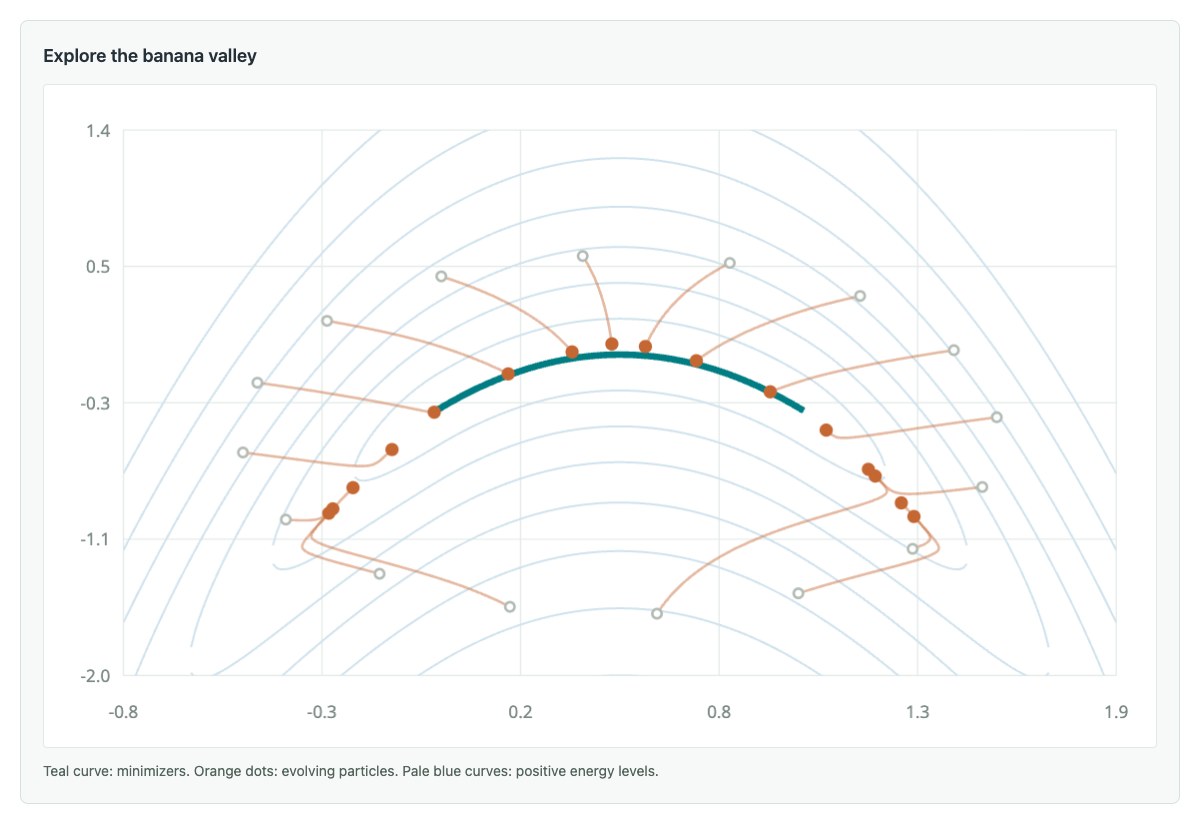
Convexity is not the only route to fast optimization. The Polyak–Łojasiewicz (P–L) condition asks for something more directly connected to gradient descent: away from the minimum value, the gradient must remain large enough.
For a differentiable function with minimum value \(f_\star\), the condition is
A collection of mathematical animations and accompanying Python notebooks, now gathered in the Mathematical Nexus.
The Mathematical Nexus brings together 800 animated vignettes and 140 accompanying Python notebooks, encompassing most of the mathematical content I have shared on social media.
The idea is to give these short explorations a more permanent home: a place where one can move from a visual intuition to the mathematics and the code behind it, and follow connections between topics.
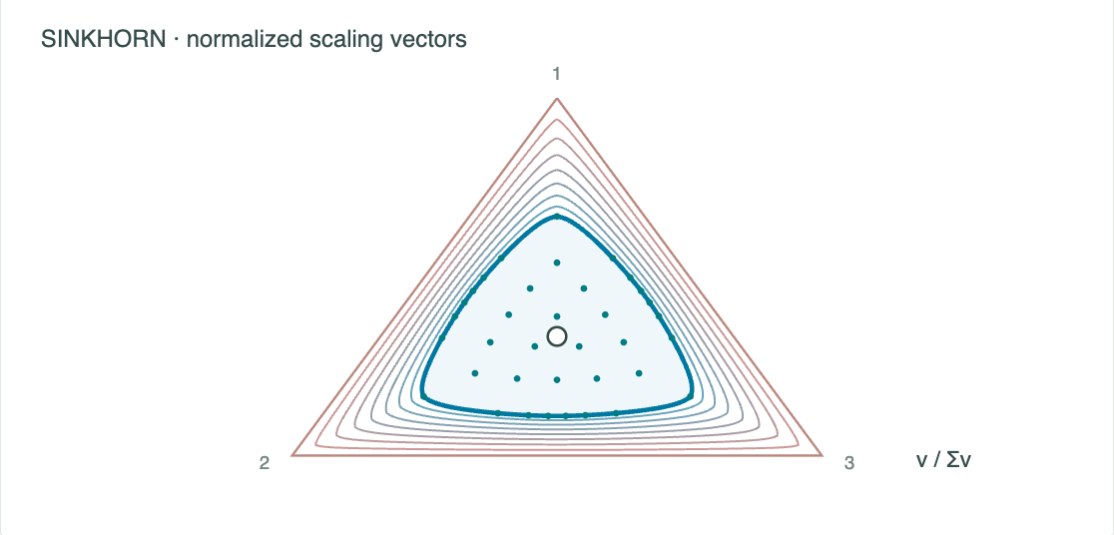
Compare a positive Markov operator with Sinkhorn’s nonlinear scaling map in an interactive simplex.
A positive Markov matrix repeatedly mixes probability vectors until they approach a single stationary distribution. Sinkhorn’s algorithm has a similar visual story: repeated application of a nonlinear map brings positive scaling vectors toward a distinguished ray.
The analogy is particularly striking on the simplex of probability vectors with three entries — a triangle. Linear mixing shrinks straight-sided triangles; Sinkhorn bends them as it contracts. The appropriate geometry for the nonlinear picture is projective.
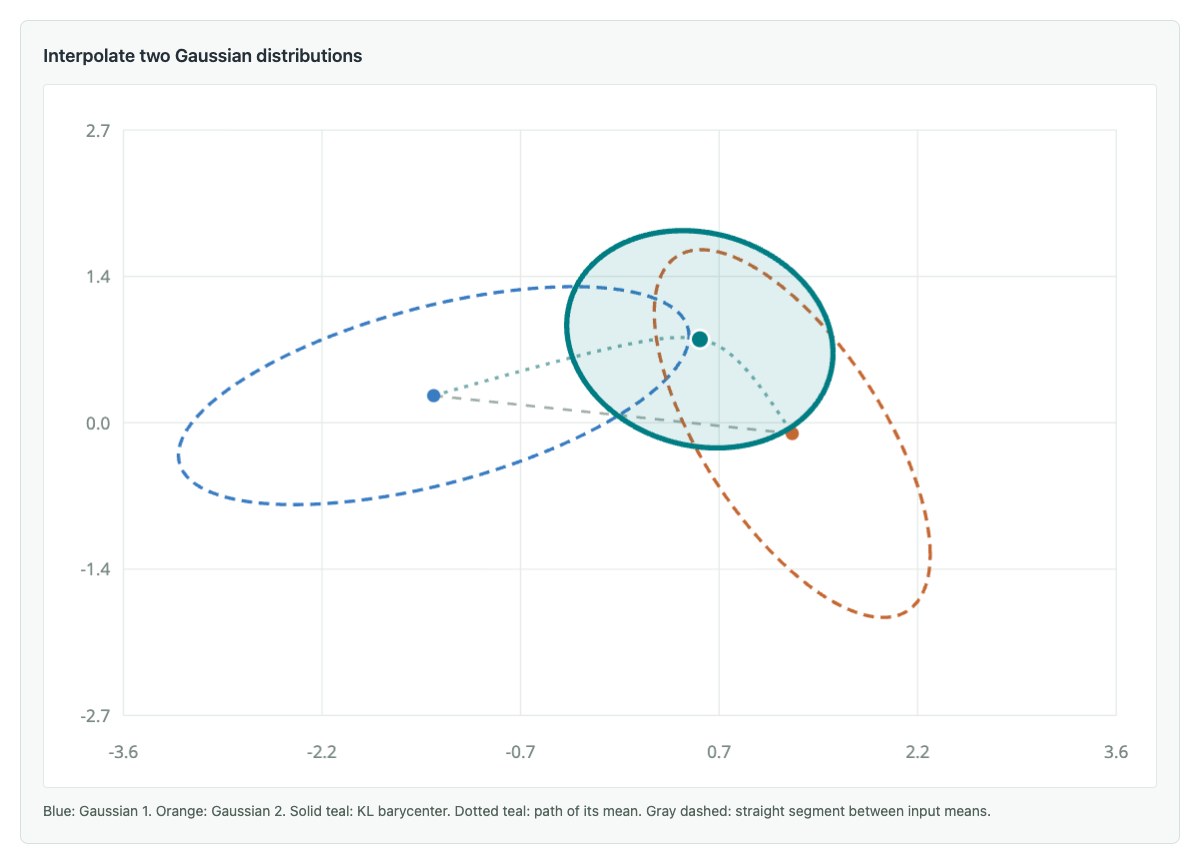
A short derivation of the reverse-KL Gaussian barycenter, with an animated two-dimensional example.
Take Gaussian distributions \(\nu_i=\mathcal N(m_i,\Sigma_i)\) with positive definite covariances, and weights \(\lambda_i\geq0\) summing to one. Their barycenter for the objective
A five-by-five matrix and an elementary proof of the gap between doubly nonnegative and completely positive matrices.
A symmetric matrix can be positive in two different senses: positive semidefinite, and nonnegative entry by entry. Requiring both gives the cone of doubly nonnegative matrices
A seemingly similar condition is to ask for a Gram factorization with nonnegative vectors. This defines the cone of completely positive matrices. The two cones agree up to dimension four — but not in dimension five.
The alpha version of my new book is online, including interactive figures.
The alpha version of my new book, Optimal Transport for Machine Learners, is out. In particular, there is an online version with interactive figures, so that the mathematical exposition can be explored alongside the examples.
This is an early version: the text and its illustrations will continue to evolve. My aim is to make the geometry and computation of optimal transport accessible to readers interested in machine learning, with the mathematics and its visual intuition close together.
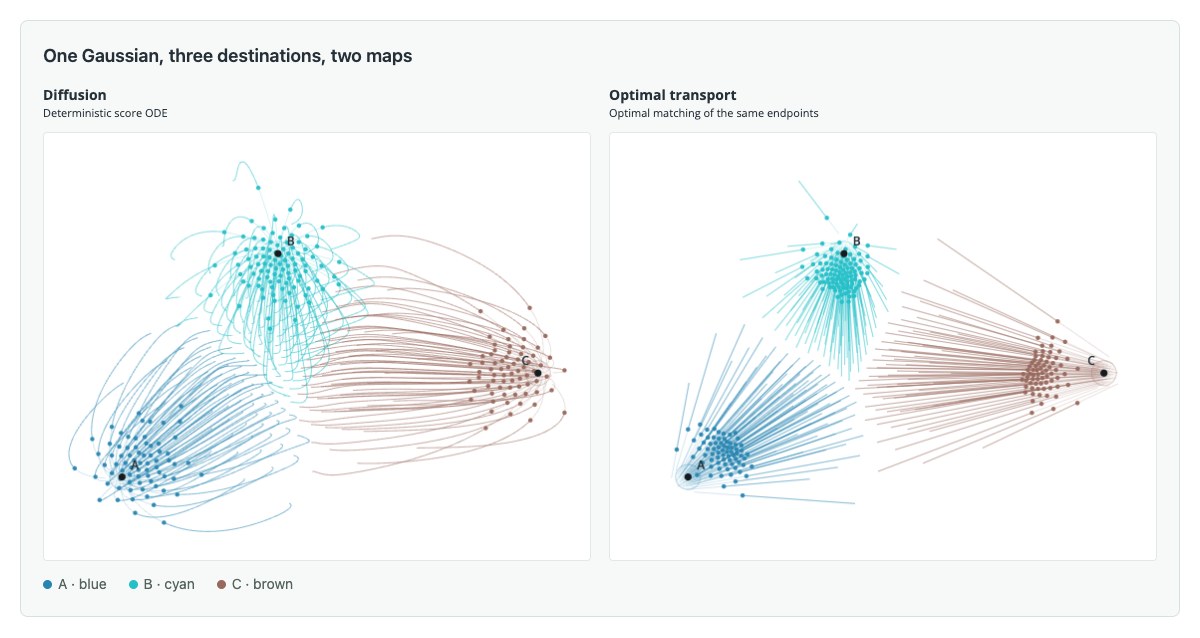
Compare the deterministic score-based probability flow with quadratic optimal transport from a centered Gaussian to a three-Gaussian mixture, down to the three-Dirac limit.
A centered Gaussian can be transformed into three Gaussian clouds in many ways. Two particularly interesting constructions are the deterministic diffusion map, obtained by reversing a score-based probability-flow ODE, and the optimal transport map, which minimizes the total squared displacement.
Both produce the same target distribution in the continuous model. But matching distributions does not mean matching individual particles. Coloring each particle by its destination makes this distinction visible.
A detailed proof that a positive convex homogeneous covariance gauge lifts to a matrix norm exactly when it is monotone.
Given a way to measure a positive semidefinite matrix, a natural way to measure a general matrix is to apply it to its Gram matrix:
\[N(X)=\sqrt{\gamma(X^\top X)}.\]
When does this construction give a norm? The key condition is monotonicity in the positive semidefinite order: increasing a covariance should not decrease its size.
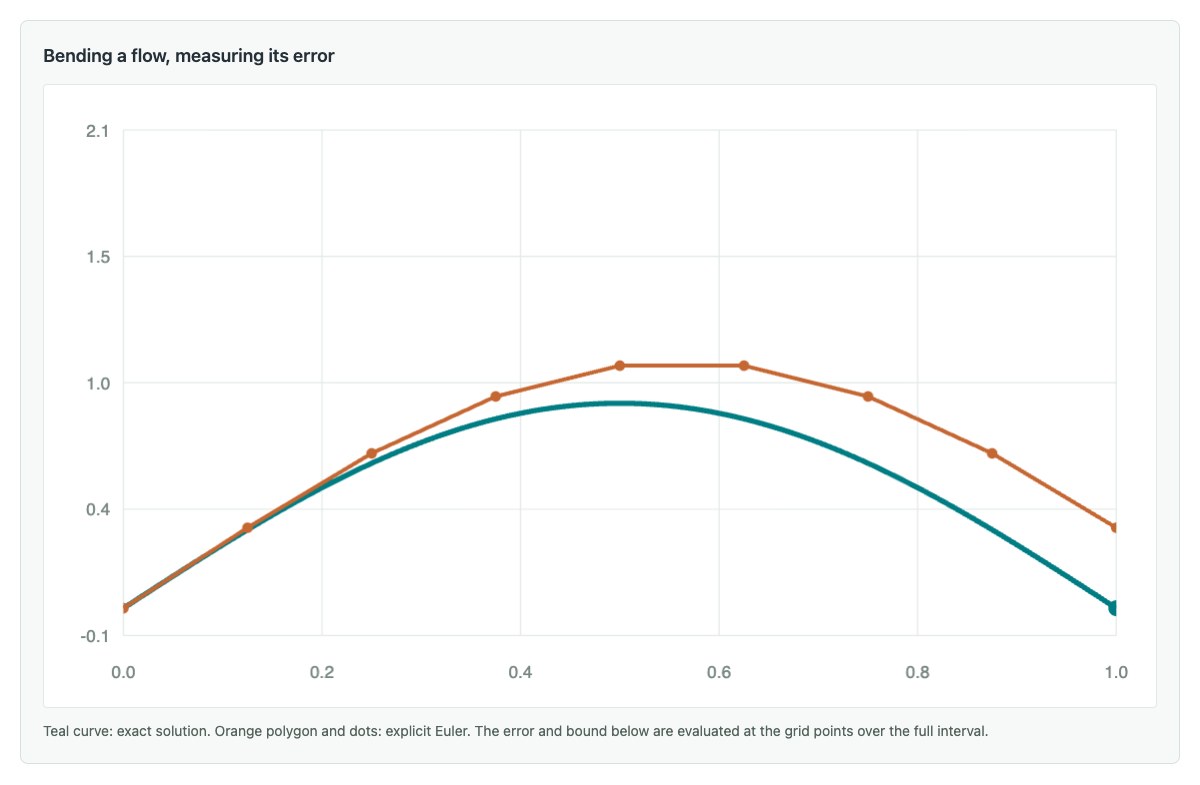
A detailed Euler error bound isolating trajectory acceleration, with a proof and an interactive example.
It is intuitively clear that straighter trajectories should be easier to integrate numerically. This intuition is especially appealing in flow matching, where one would like to generate samples with as few velocity evaluations as possible.
I wanted a precise estimate that exhibits this dependence directly. Rewriting the usual stability argument behind Cauchy–Lipschitz gives one: Euler’s global error is controlled by the material acceleration along the exact trajectory, multiplied by a stability factor.
An explicit solution of UYU = X, with proofs of uniqueness and smooth dependence on positive definite matrices.
For positive numbers, solving \(uyu=x\) is easy: \(u=\sqrt{x/y}\). What remains true when the variables are matrices, which need not commute?
If \(X\) and \(Y\) are symmetric positive definite, there is still exactly one symmetric positive definite solution of \(UYU=X\). More surprisingly, for fixed \(Y\), the correspondence between \(U\) and \(X\) is a global smooth change of coordinates on the positive definite cone.
Why every linear rank preserver is a left-right change of basis, possibly composed with transposition in the square case.
Fun fact: a linear operator on matrices may mix all their entries, but preserving the rank of every matrix leaves remarkably little freedom. It must be a change of basis on the left and on the right.
There is just one additional possibility for square matrices: transposition, followed by those same changes of basis. The proof comes from understanding the linear subspaces made entirely of matrices of rank at most one.
I have the pleasure of sharing my office with Olivier, so I was able to witness the creation of this fantastic book. Seeing the finished result is therefore particularly special.